Part 1: Finite Differences and Discrete Calculus
Foundations of Discrete Computing | Numerical Methods Module 1 | COMP 521
Learning Objectives
By the end of this section, you will be able to:
Explain why a computer cannot take the mathematical limit and distinguish that ideal from the numerical approximation we actually compute.
Derive forward, backward, central, and fourth-order central finite-difference formulas from Taylor series with clean error terms.
Analyze the total-error balance between truncation error and floating-point round-off error and estimate an appropriate step size .
Implement robust finite-difference utilities with validation for invalid step sizes, unknown methods, and non-finite function values.
Predict how accuracy changes with method choice, function smoothness, and physical scale before you run code.
Introduction: Why Numerical Derivatives Matter
Why this matters: numerical derivatives are not a side topic in computational astrophysics. They sit inside orbit integration, stellar structure, radiative transfer, optimization, and data analysis.
In continuous mathematics, derivatives tell us how a quantity changes at an instant. In computational science, we almost never have access to that exact instantaneous limit. We have function values at nearby points, finite precision arithmetic, and algorithms that must make a choice about how close is “close enough.”
Derivatives appear everywhere in the astrophysical problems we care about:
Kinematics: if is position in cm, AU, or pc, then
is velocity in , and
is acceleration in . These derivatives drive -body dynamics.
Stellar structure: the equations for a star involve gradients such as
where is pressure in , is temperature in K, is enclosed mass in g or , and is radius in cm.
Radiative transfer: if is specific intensity in , then
describes how intensity changes along path length in cm. In this reading we use as an attenuation coefficient in , so must have units of intensity per unit length, .
Orbital dynamics and optimization: when we estimate derivatives of an energy function, a likelihood, or a residual, the numerical derivative is often the first thing we compute when an analytical derivative is inconvenient or unavailable.
Most real scientific problems do not hand us a closed-form answer. We discretize, approximate, and compute. That move from the continuous world to the discrete world is where the central paradox of this reading lives.
The Core Problem
Why this matters: if you do not understand the core derivative paradox, every later conversation about truncation error, round-off error, and algorithm design will feel like disconnected rules.
The mathematical definition of the derivative is
This equation is compact, but it mixes three ideas that we must separate carefully:
Mathematical ideal: the derivative is defined by the limit .
Numerical approximation: on a computer, we use a finite value of and approximate that limit.
Floating-point limitation: if becomes too small, subtraction and rounding errors destroy the accuracy of the approximation.
Mathematics wants ; computers require .
Here is a compact worked example before we derive anything formal. Let
The exact derivative is
so at the true answer is .
If we use the forward-difference idea with ,
If we shrink to ,
The approximation improves as gets smaller, but it is still not exact because we have not taken the true limit.
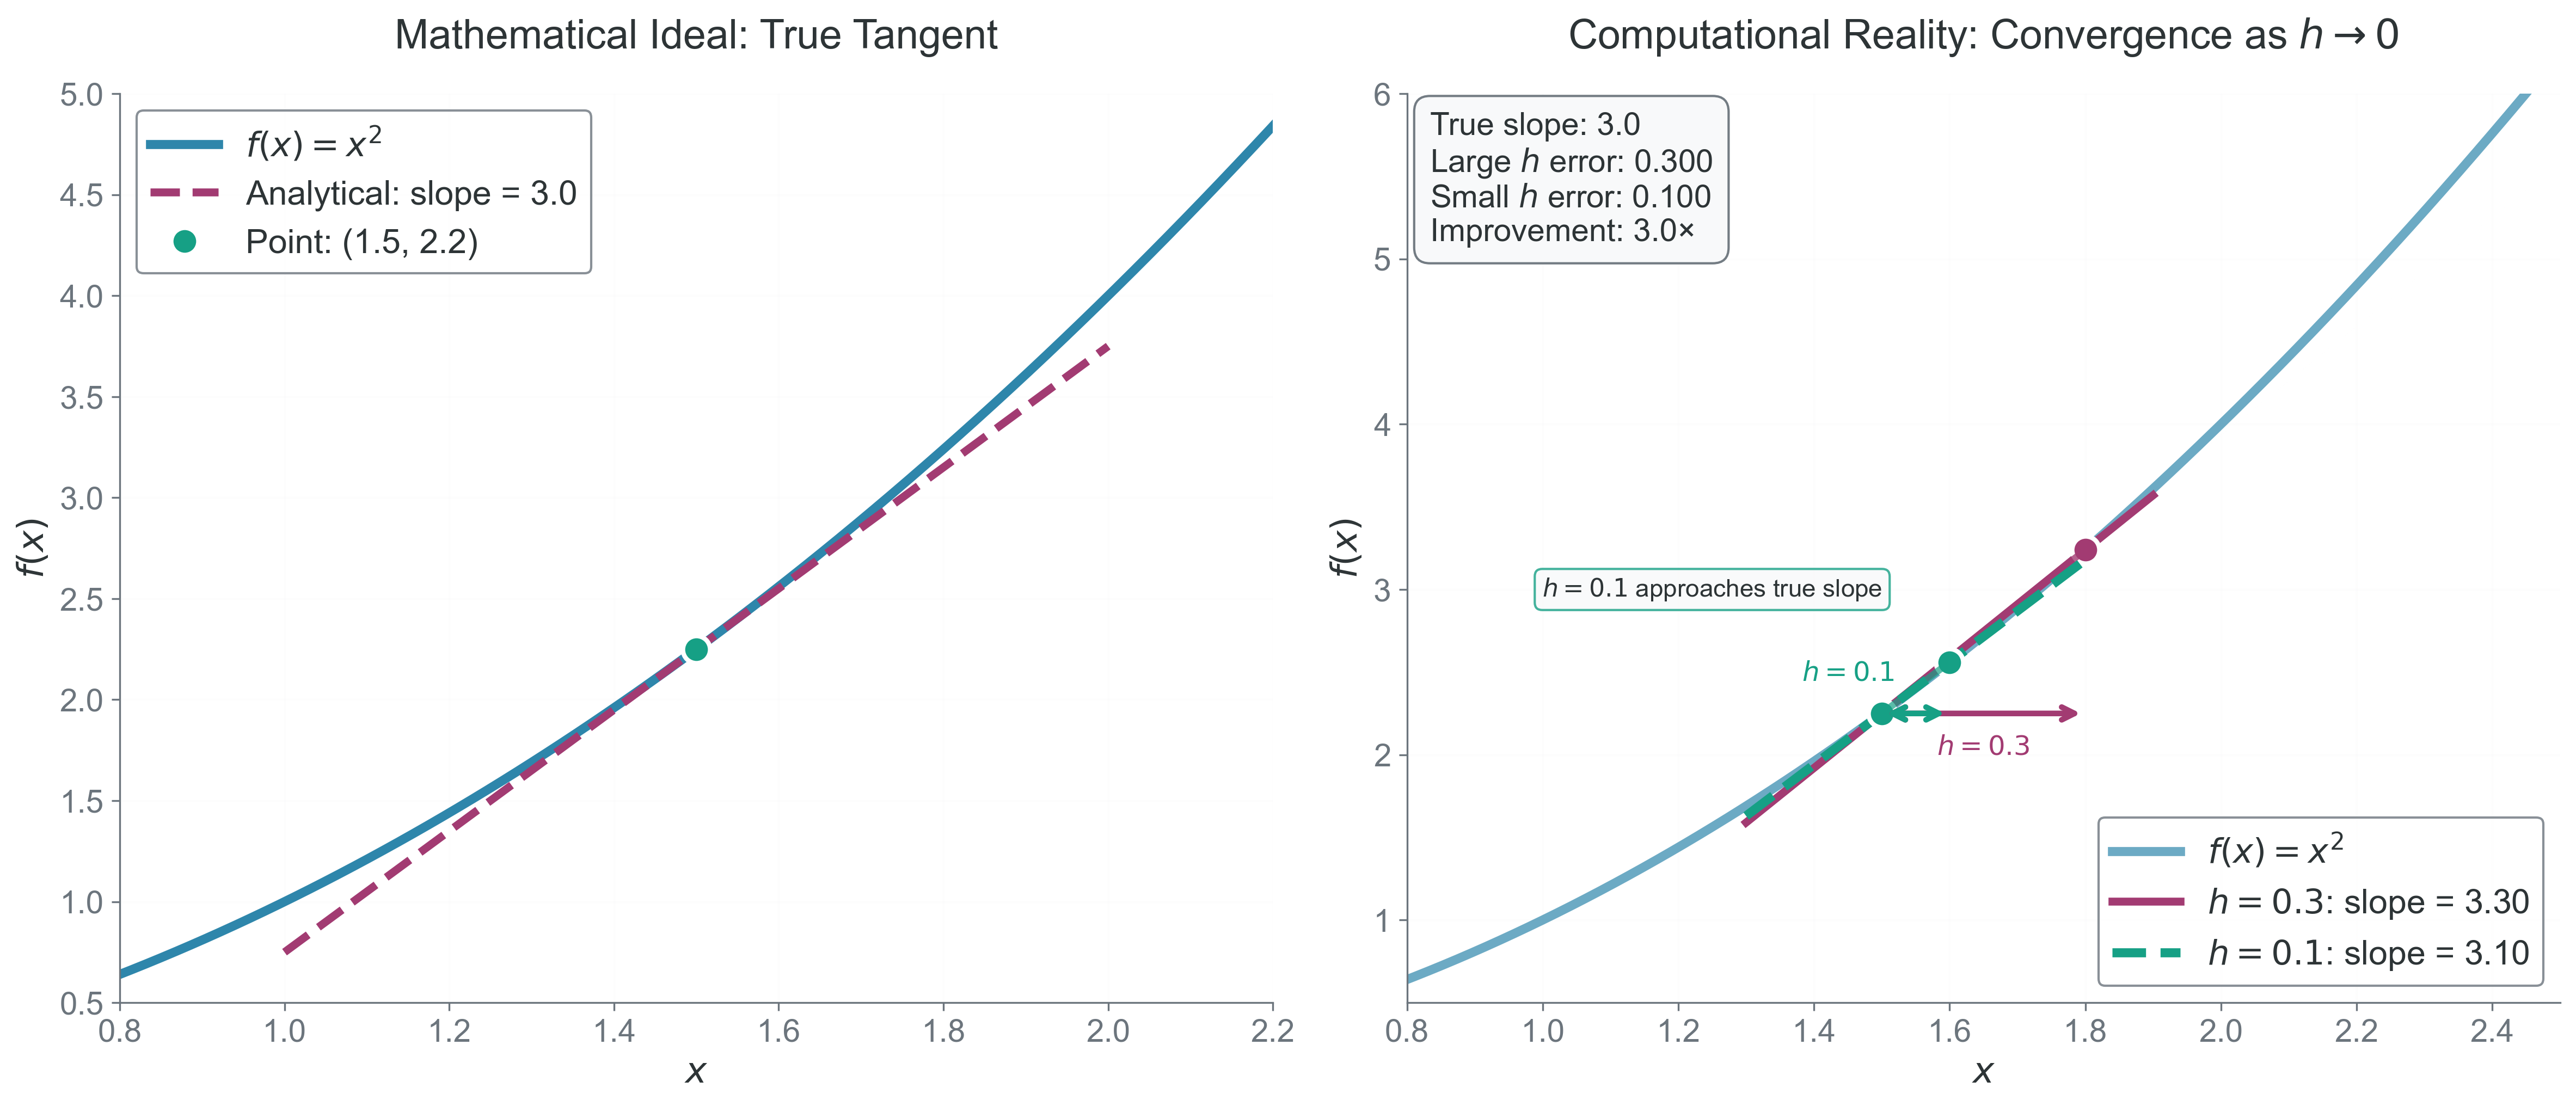
Figure 1:What to notice: as shrinks, the secant slope moves toward the tangent slope, but the figure never lets the discrete secant become the exact limit. That visual gap is the paradox of numerical differentiation: smaller improves the approximation, but the computer still works with a finite step.
On a real computer, we also need to remember that numbers are stored in floating-point form. Double precision gives roughly 16 decimal digits of relative precision near numbers of order unity, but that does not mean every subtraction preserves 16 useful digits.
If is too small, then may round to the same floating-point value as . If and are nearly equal, the subtraction
can lose most of the significant digits we care about. This is catastrophic cancellation.
Answers and reasoning
For , the forward quotient is exactly in real arithmetic. Reducing from 0.5 to 0.1 reduces that truncation error by five.
A finite step samples another point; zero gives a zero denominator. A limit describes the behavior of finite steps, not an instruction to divide by zero.
If both evaluations round to the same value, the numerator is zero and the derivative estimate can be wrong even though the code returns a finite number.
Intuition: Why Taylor Series?
Why this matters: Taylor series gives us a controlled way to connect a continuous function to nearby discrete samples. It is the mathematical bridge between calculus and computation.
Student mental model: Taylor series is a local decoder ring. It tells us exactly what information is hidden inside the nearby function values , , , and so on.
Around the point , the Taylor expansion of a smooth function is
This equation says that the value at contains the function value, the slope, the curvature, and higher-order corrections. Computationally, that is exactly what we need: if we rearrange this expansion, we can isolate and understand the error we introduce when we truncate the rest.
The backward expansion is equally important:
Now we have a menu of nearby samples, and we can combine them in clever ways. Some combinations keep the error term. Others cancel it. The design of a finite-difference formula is really the design of a Taylor-series cancellation pattern.
Forward Difference
Why this matters: forward difference is the simplest derivative approximation, and it appears naturally whenever we only know values at the current point and points ahead.
The forward Taylor expansion is
This expansion tells us how a one-sided sample at mixes the derivative we want with curvature and higher-order contamination.
Subtract from both sides:
The left-hand side is now a computable change in the function value over one forward step.
Now divide by :
This turns the finite change into a secant slope, while the remaining Taylor terms reveal the bias we introduced.
Finally, solve for the derivative:
So the forward-difference approximation is
This means the leading truncation error is proportional to , so forward difference is a first-order method:
Computationally, that statement tells us that halving only halves the leading truncation error. Forward difference is simple and useful, but not especially accurate.
For the earlier quadratic example with , , and , we found the approximation 6.1 instead of 6.0. That 0.1 error is exactly the kind of first-order behavior the Taylor analysis predicts.
The leading term is the computational price of using a one-sided stencil: curvature leaks directly into the estimate.
Forward difference is simple, but its one-sided bias leaves a first-order error.
Backward Difference
Why this matters: backward difference becomes the natural choice near right-hand boundaries, or whenever “past” values are available but “future” values are not.
Start from the backward Taylor expansion:
This time we are reading the same local information from the point behind instead of the point ahead of it.
Rearrange:
Again, the goal is to isolate a computable finite change before dividing by the step size.
Then divide by :
This secant slope now looks backward, so the sign of the leading bias changes.
Solving for gives
So the backward-difference approximation is
Like forward difference, backward difference has first-order truncation error:
The sign of the leading error term differs from the forward case, but the key computational message is the same: this method is still first-order accurate.
Backward difference has the same order as forward difference; only the direction changes.
Central Difference
Why this matters: central difference is the default first derivative in many scientific codes because symmetry cancels the largest truncation term.
Student mental model: forward and backward difference each lean to one side. Central difference stands in the middle and asks the left and right samples to balance each other.
Write both Taylor expansions:
This first expansion shows what the forward sample contributes.
The backward sample contains the same even-power terms, which is exactly what symmetry needs in order to cancel them.
Subtract the second equation from the first:
The even-power terms disappear, so the largest truncation contribution is now much smaller.
Now divide by :
This symmetric secant slope already has second-order accuracy built into it.
Solving for gives
So the central-difference approximation is
Its leading truncation error is proportional to :
Computationally, that means halving reduces the leading truncation error by about a factor of 4, not just a factor of 2.
For , central difference at is especially illuminating:
For a quadratic, the method is exact because the odd-power cancellation leaves no truncation error in the first derivative estimate.
Central difference uses symmetry to cancel the largest truncation term.
The Power of Symmetry
Why this matters: symmetry is one of the most powerful accuracy upgrades in numerical analysis, and central difference is your first clear example of it.
Central difference improves accuracy by pairing points symmetrically around . Even-order terms in the Taylor expansions cancel, leaving a smaller leading error term. Symmetry therefore changes the truncation order without changing the underlying approximation problem.
This pattern appears again and again:
centered finite differences for derivatives,
Simpson’s rule in numerical integration,
symmetric time integrators in dynamics,
paired sampling tricks in Monte Carlo methods.
What symmetry is really buying you is cancellation of systematic bias. In computational language: the approximation is still finite, but it is less one-sided.
Higher-Order Methods
Why this matters: when the function is smooth and extra function evaluations are affordable, higher-order methods can reduce truncation error dramatically.
By combining more Taylor expansions, we can cancel more unwanted terms. A standard fourth-order central difference for the first derivative is
Its leading truncation error behaves like
Computationally, this formula spends more function evaluations to buy a much smaller truncation error in the smooth-function regime. That trade is often worthwhile, but only if round-off and function noise do not dominate first.
If the function is noisy, non-smooth, or expensive to evaluate, higher order is not automatically better. A formally high-order method can still perform worse in practice if the assumptions behind the Taylor expansion are not satisfied.
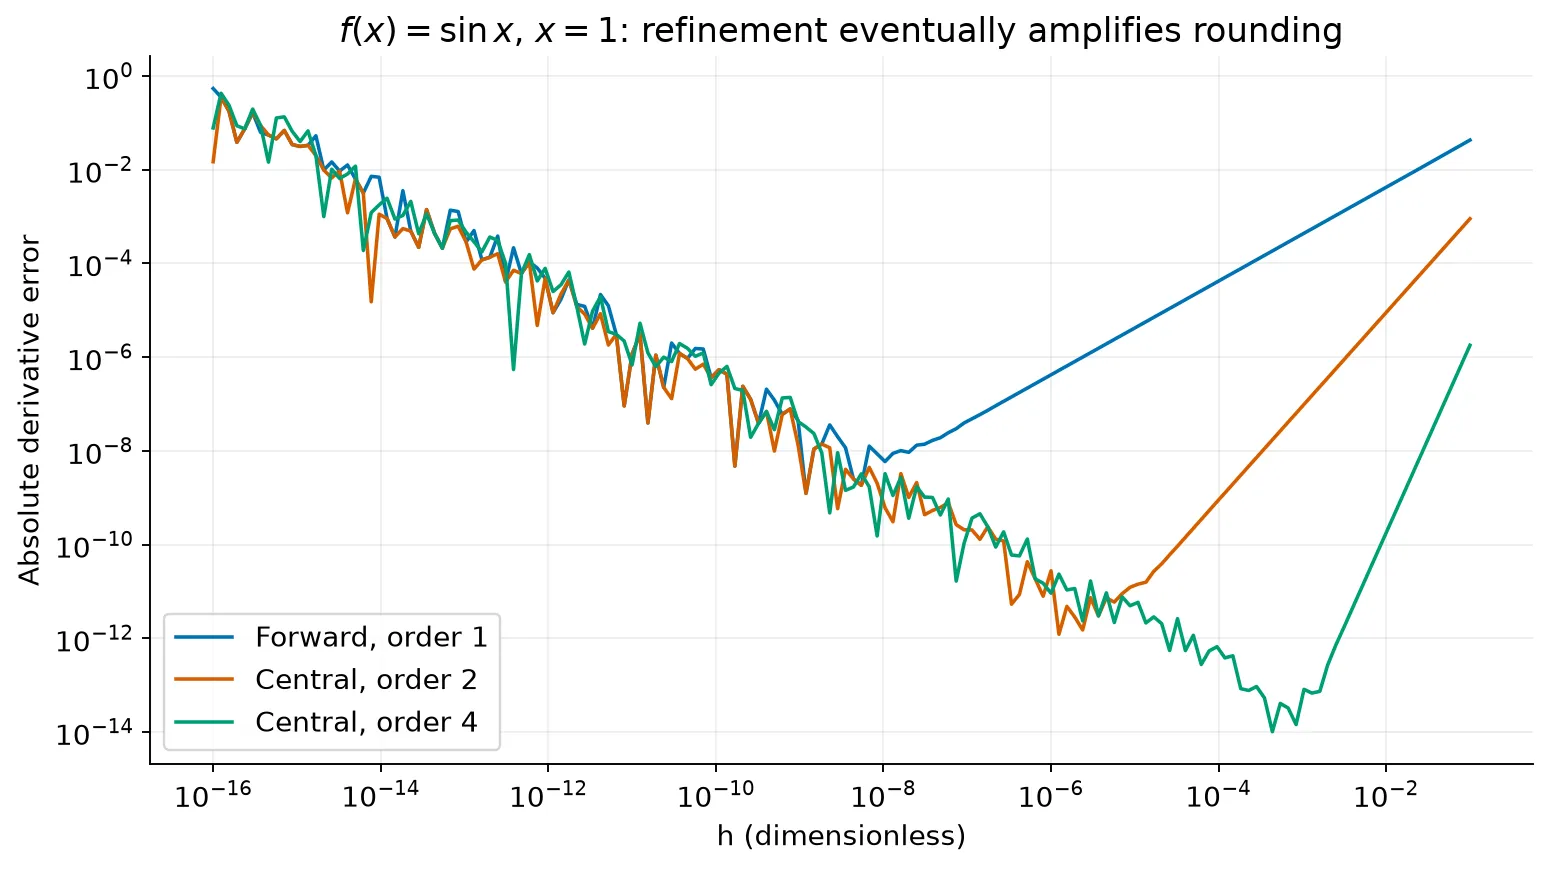
Figure 2:What to notice: the right-hand truncation regime has slopes that match the theory — forward behaves like , central like , and fourth-order central like . The left-hand round-off upturn shows why higher order does not rescue you once subtraction error dominates.
The Fundamental Trade-off / Optimal 
Why this matters: the best step size is not “the smallest one you can think of.” It is the one that balances two different error mechanisms.
There are two competing effects:
Truncation error decreases as decreases.
Round-off error usually grows like because we subtract nearly equal numbers and then divide by a small step.
For forward difference, the leading truncation and round-off model is
This equation says that one part of the error prefers smaller , while the other prefers larger . The total error curve is therefore U-shaped.
Differentiate with respect to and set the derivative to zero:
Solving for the minimizing step size gives
If the local scales of and are comparable for a particular problem, then forward difference often lands near
In double precision, that is roughly 10-8. This is order-of-magnitude guidance for well-scaled smooth problems, not a universal law for every function.
For central difference, the truncation term is smaller, so the model changes to
Now the minimizing step size is
So central difference typically prefers
which is larger than the forward-difference optimum. Computationally, that is excellent news: central difference is both more accurate in truncation error and less sensitive to having an extremely tiny step.
For a fourth-order central derivative, the same balancing logic leads to the scaling
That scaling will appear again in the executable code below, but again as heuristic guidance rather than a guaranteed best choice for every function and every scale.
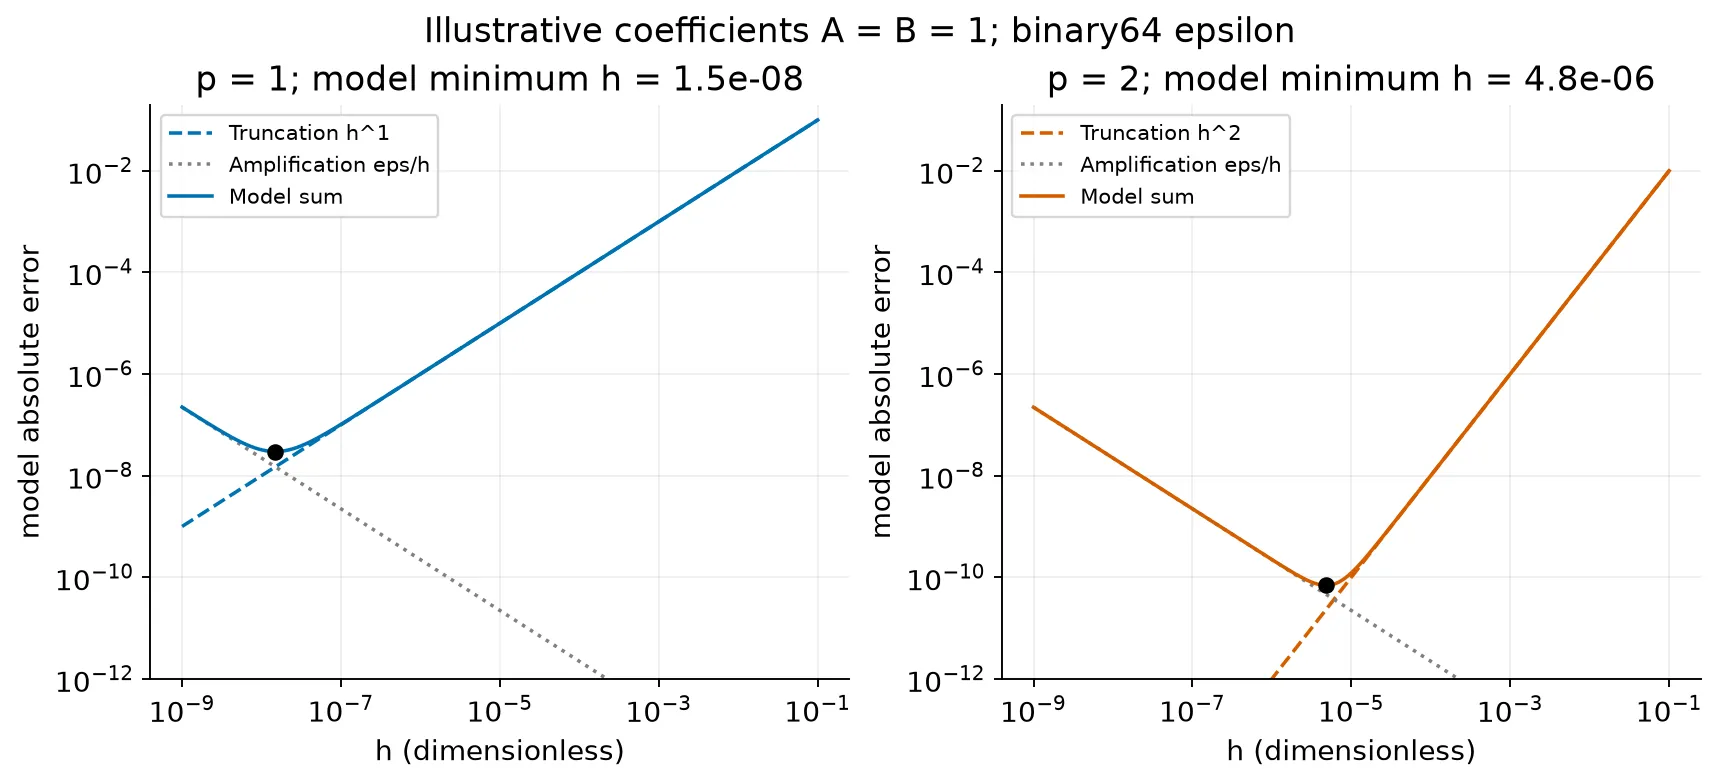
Figure 3:Both minima are visible. The curves use the illustrative model with and binary64 machine epsilon. Dashed curves show truncation; dotted curves show amplified rounding; solid curves show their sum. Differentiating this model gives . The minimum changes with the coefficients as well as the order. Actual function-evaluation errors can be irregular and can partly cancel, so these are explanatory curves, not fitted error guarantees. Compare them with the executable refinement experiment below.
For forward difference in double precision, it is common to get on the order of 8 correct digits in a well-scaled smooth problem. That is useful guidance, but it is not a universal accuracy ceiling for every derivative calculation.
The best is a balance between truncation and round-off, not the smallest possible step.
Before running any examples below, we need one shared setup cell. It defines the imports and helper functions used throughout the rest of the reading, so if you restart the kernel this is the first cell to rerun.
import math
from typing import Callable

import matplotlib.pyplot as plt
import numpy as np


def _checked_function_value(f: Callable[[float], float], point: float) -> float:
    """Evaluate a scalar function and reject non-finite outputs."""
    value = float(f(point))
    if not np.isfinite(value):
        raise ValueError(
            f"Function evaluation produced a non-finite value at x = {point:.6e}."
        )
    return value


def finite_diff(
    f: Callable[[float], float],
    x: float,
    h: float,
    method: str = "central",
) -> float:
    """Estimate the derivative of a scalar function with a finite-difference stencil."""
    if not np.isfinite(h) or h <= 0:
        raise ValueError("Step size h must be positive and finite.")
    if not np.isfinite(x):
        raise ValueError("x must be finite.")

    method_name = method.lower()
    valid_methods = {"forward", "backward", "central", "central4"}
    if method_name not in valid_methods:
        raise ValueError(
            f"Unknown method '{method}'. Expected one of {sorted(valid_methods)}."
        )

    if method_name == "forward":
        f_x = _checked_function_value(f, x)
        f_x_plus_h = _checked_function_value(f, x + h)
        return (f_x_plus_h - f_x) / h

    if method_name == "backward":
        f_x = _checked_function_value(f, x)
        f_x_minus_h = _checked_function_value(f, x - h)
        return (f_x - f_x_minus_h) / h

    if method_name == "central":
        f_x_plus_h = _checked_function_value(f, x + h)
        f_x_minus_h = _checked_function_value(f, x - h)
        return (f_x_plus_h - f_x_minus_h) / (2.0 * h)

    f_x_plus_2h = _checked_function_value(f, x + 2.0 * h)
    f_x_plus_h = _checked_function_value(f, x + h)
    f_x_minus_h = _checked_function_value(f, x - h)
    f_x_minus_2h = _checked_function_value(f, x - 2.0 * h)
    return (-f_x_plus_2h + 8.0 * f_x_plus_h - 8.0 * f_x_minus_h + f_x_minus_2h) / (
        12.0 * h
    )


def finite_diff_error(true_value: float, approx_value: float) -> dict[str, float]:
    """Return absolute and relative error for a derivative estimate."""
    true_scalar = float(true_value)
    approx_scalar = float(approx_value)

    if not np.isfinite(true_scalar) or not np.isfinite(approx_scalar):
        raise ValueError("Both true_value and approx_value must be finite.")

    absolute_error = abs(approx_scalar - true_scalar)
    relative_error = (
        absolute_error / abs(true_scalar) if true_scalar != 0.0 else math.nan
    )
    return {
        "absolute_error": absolute_error,
        "relative_error": relative_error,
    }


def practical_optimal_h(
    x: float,
    method: str = "central",
    epsilon: float = np.finfo(float).eps,
) -> float:
    """Choose a scale-aware step size based on floating-point precision."""
    if epsilon <= 0 or not np.isfinite(epsilon):
        raise ValueError("epsilon must be a positive finite floating-point value.")

    method_name = method.lower()
    if method_name in {"forward", "backward"}:
        exponent = 0.5
    elif method_name == "central":
        exponent = 1.0 / 3.0
    elif method_name == "central4":
        exponent = 1.0 / 5.0
    else:
        raise ValueError(
            "Unknown method. Expected 'forward', 'backward', 'central', or 'central4'."
        )

    x_scale = max(abs(float(x)), 1.0)
    return (epsilon**exponent) * x_scale
Interactive Exploration
Why this matters: the best way to internalize the error trade-off is to vary yourself and watch different methods succeed or fail.
In COMP 521, we do this exploration directly in executable Python rather than through a separate browser demo. The goal is the same: choose a function, a point , a method, and a log-scaled step size , then compare what your prediction says to what the calculation actually does.
This cell reuses the shared helper functions defined earlier. It computes the absolute derivative error for three methods, and you should expect a right-hand truncation regime, a left-hand round-off upturn, and lower curves for higher-order methods while the smooth-function assumptions hold.
exploration_function = np.sin
exploration_label = "sin(x)"
exploration_x = 1.0
exploration_h_values = np.logspace(-16, -1, 80)
true_derivative = float(np.cos(exploration_x))

fig, ax = plt.subplots(figsize=(8, 5))
for method_name in ["forward", "central", "central4"]:
    abs_errors = []
    for h_value in exploration_h_values:
        approx = finite_diff(exploration_function, exploration_x, h_value, method_name)
        error_summary = finite_diff_error(true_derivative, approx)
        abs_errors.append(error_summary["absolute_error"])

    ax.loglog(exploration_h_values, abs_errors, marker="o", markersize=3, label=method_name)

ax.set_xlabel("Step size $h$")
ax.set_ylabel("Absolute derivative error")
ax.set_title(f"Guided exploration for $f(x) = {exploration_label}$ at $x = {exploration_x}$")
ax.grid(True, which="both", alpha=0.3)
ax.legend(title="Method")
plt.show()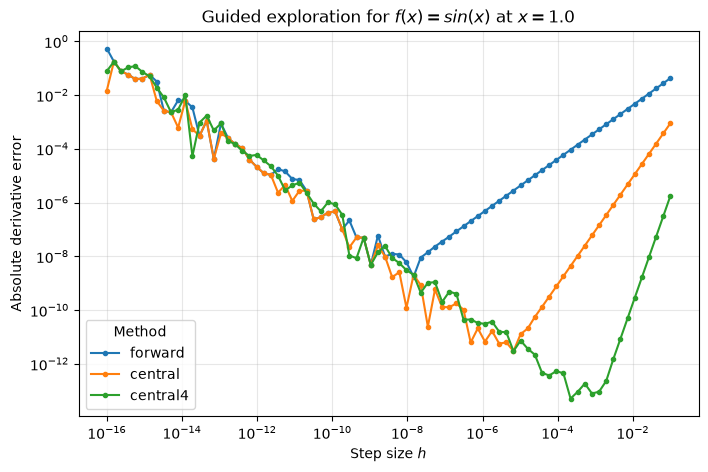
What to notice: for large , the right side of each curve is truncation-dominated, and the slopes reflect method order. As becomes extremely small, each curve turns upward because round-off takes over. The minimum of each curve is the computational version of the U-shaped total-error story.
Interpretation: the right side of the plot is the truncation regime, where method order controls the slope. The left-side upturn is round-off error. The bottom of each curve is the experimentally visible version of the U-shaped total-error logic from the previous section.
Practical Algorithm for Choosing 
Why this matters: in real code, you rarely know or ahead of time, so you need a practical scale-aware heuristic instead of the exact symbolic optimum.
The most important practical idea is that should scale with the magnitude of the problem. A step size that makes sense near does not make sense automatically near .
This section reuses the shared helper functions defined earlier. The point now is not to re-read the implementation, but to watch how a scale-aware heuristic behaves on concrete examples.
Worked Example 1: at 
Why this matters: this is the cleanest first test because the exact derivative is simple and central difference on a quadratic exposes the power of symmetry immediately.
The exact derivative is
so at ,
This gives us an exact reference value, so the only question is how each stencil misses it.
This cell reuses the shared helper functions defined earlier. It computes three derivative estimates at the same , and you should expect forward and backward to lean in opposite directions while central benefits from symmetry.
f_quadratic = lambda x: x**2
x0 = 3.0
h0 = 0.1
true_value = 2.0 * x0

quadratic_results = {}
for method_name in ["forward", "backward", "central"]:
    approx = finite_diff(f_quadratic, x0, h0, method=method_name)
    quadratic_results[method_name] = finite_diff_error(true_value, approx)
    print(
        f"{method_name:8s} approx = {approx:6.3f}  "
        f"abs error = {quadratic_results[method_name]['absolute_error']:.3e}"
    )

# Expected pattern:
# - forward is slightly high,
# - backward is slightly low,
# - central is exact for this quadratic.
forward approx = 6.100 abs error = 1.000e-01
backward approx = 5.900 abs error = 1.000e-01
central approx = 6.000 abs error = 5.329e-15
Interpretation: forward and backward differences lean in opposite directions because they are one-sided. Central difference lands exactly on the true derivative here because the symmetry cancels the relevant truncation term for a quadratic.
Worked Example 2: at 
Why this matters: this example is smooth, familiar, and lets us see how the same method behaves across several choices of .
The exact derivative is
so at ,
This gives us a smooth benchmark where shrinking helps at first and then eventually hurts.
This cell reuses the shared helper functions defined earlier. It checks one method across several step sizes, and the important pattern is the improvement-then-breakdown sequence rather than any single printed number.
f_sine = np.sin
x1 = 1.0  # radians
true_sine_derivative = float(np.cos(x1))
h_values = [1e-1, 1e-3, 1e-6, 1e-10]

print("Method = central")
for h_value in h_values:
    approx = finite_diff(f_sine, x1, h_value, method="central")
    errors = finite_diff_error(true_sine_derivative, approx)
    print(
        f"h = {h_value:>8.1e}  approx = {approx:.12f}  "
        f"abs error = {errors['absolute_error']:.3e}"
    )

# Expected pattern:
# the approximation improves at first, then eventually gets worse when h is too small.
Method = central
h = 1.0e-01 approx = 0.539402252170 abs error = 9.001e-04
h = 1.0e-03 approx = 0.540302215818 abs error = 9.005e-08
h = 1.0e-06 approx = 0.540302305896 abs error = 2.772e-11
h = 1.0e-10 approx = 0.540302247387 abs error = 5.848e-08
Interpretation: shrinking helps only until round-off error becomes important. That turning point is the numerical version of the paradox we started with.
Worked Example 3: Why Must Scale With the Problem
Why this matters: in astrophysics, the same code often sees variables that differ by many orders of magnitude. A single hard-coded is rarely defensible.
Consider these representative scales:
,
,
.
If is a radius or mass coordinate, the perturbation should reflect the size of that coordinate. A dimensionless means very different things at those scales.
This cell reuses the shared helper functions defined earlier. It computes scale-aware step sizes for three representative coordinates, and you should expect the recommended perturbation to grow with the magnitude of the physical variable.
astronomical_scales = {
    "lab length (cm)": 1.0,
    "orbital radius (1 AU in cm)": 1.496e13,
    "enclosed mass (1 Msun in g)": 1.989e33,
}

for label, scale_value in astronomical_scales.items():
    h_forward = practical_optimal_h(scale_value, method="forward")
    h_central = practical_optimal_h(scale_value, method="central")
    print(
        f"{label:28s}  x = {scale_value:.3e}  "
        f"h_forward = {h_forward:.3e}  h_central = {h_central:.3e}"
    )

# Expected pattern:
# the chosen h scales with |x|, so large physical coordinates receive proportionally larger steps.
lab length (cm) x = 1.000e+00 h_forward = 1.490e-08 h_central = 6.055e-06
orbital radius (1 AU in cm) x = 1.496e+13 h_forward = 2.229e+05 h_central = 9.059e+07
enclosed mass (1 Msun in g) x = 1.989e+33 h_forward = 2.964e+25 h_central = 1.204e+28
Interpretation: the algorithm is not claiming these are physically perfect step sizes for every application. It is enforcing a necessary first principle: a numerically meaningful perturbation should scale with the magnitude of the quantity being perturbed.
Bridge to Part 2
Why this matters: we have treated round-off error as a real force in the problem, but we have not yet unpacked where it comes from.
You now know the central paradox of numerical differentiation:
the derivative is defined by a limit,
the computer replaces that limit with a finite stencil,
floating-point arithmetic sets a hard floor on how much accuracy that stencil can deliver.
In Part 2, we will zoom in on the floating-point system itself. We will look at machine epsilon directly, see why decimal intuition fails in binary arithmetic, and study the mechanisms behind catastrophic cancellation and error propagation. That is the next layer of the same story, not a separate topic.
Next: Part 2 - Numbers Aren’t Real